The best audio file formats for speech-to-text: A guide
Learn about the best audio and video formats for speech-to-text applications, as well as best practices for audio post-processing techniques.
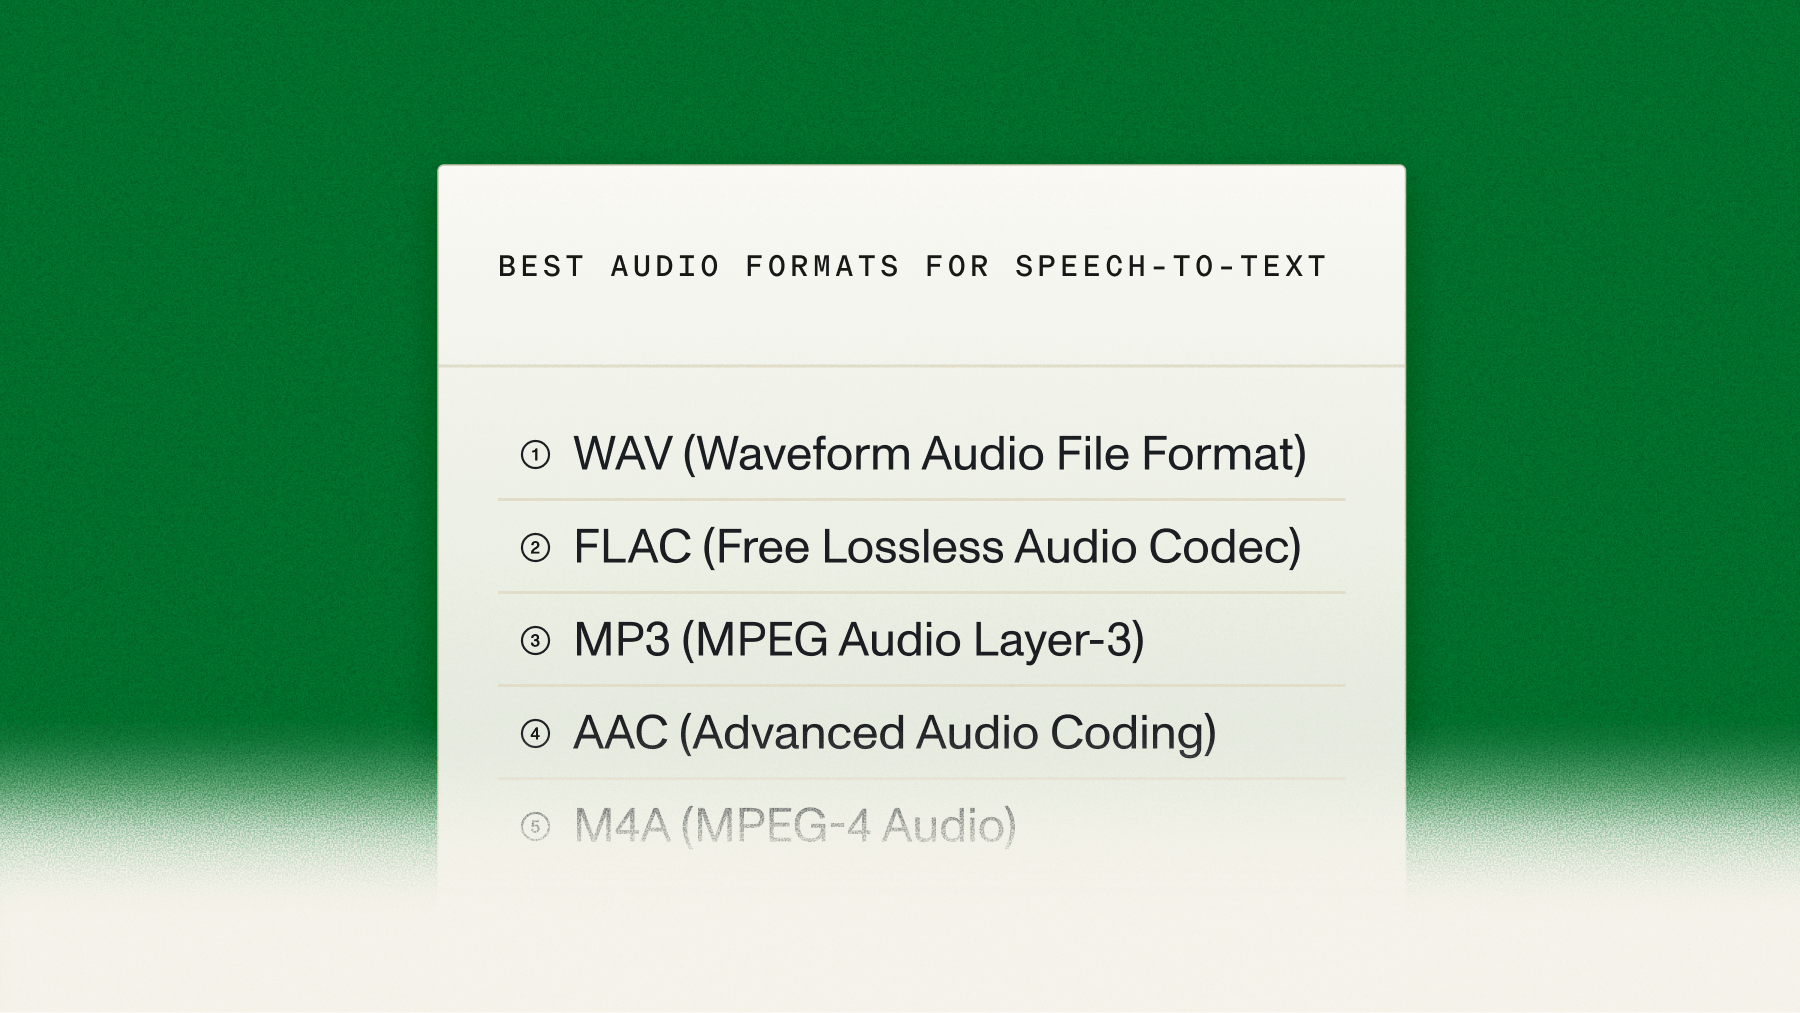
WAV and FLAC are the best audio file formats for speech-to-text. MP3, AAC, and M4A are also fine for most work. That's the short version, and for a lot of projects it's the whole answer.
The longer version is more interesting, because the format question is almost never really about the format. It's about what happened to the audio before it reached you — the sample rate it was captured at, the bitrate it got squeezed through, whether four speakers got mixed down into one channel. Those decisions shape accuracy far more than the file extension does.
So here's how to choose, what genuinely degrades a transcript, and the size and duration limits you'll hit before any of it matters.
Which audio file format is best?
It depends on what the file is for. WAV is best when quality is the priority and you control the recording. FLAC is best for archives and large batch pipelines. AAC is the best lossy format for anything moving across a network, and MP3 wins only on universal compatibility.
For general listening, that table is the end of the discussion. For automatic speech recognition, the ranking tightens, because a model isn't listening for warmth or stereo imaging. It's listening for consonants.
What actually makes a format good for speech-to-text
Three variables matter, and none of them is the file extension.
Sample rate. 16 kHz is the standard for speech recognition, and it's enough. Nearly all the acoustic information that distinguishes one phoneme from another sits below 8 kHz, and a 16 kHz sample rate captures it. Anything above that is headroom you're paying to store. Upsampling an 8 kHz phone call to 48 kHz adds file size and zero information.
Bit depth. 16-bit is the practical minimum. It gives you enough dynamic range that a quiet speaker at the far end of a conference table doesn't get buried in the quantization floor. 8-bit audio is where transcripts start losing whole words.
Channels. Mono is fine for a single speaker. Where multichannel earns its keep is a call recording with each participant on a separate track — then you get speaker attribution for free, no diarization required. Our speech understanding features handle multichannel audio directly.
The one thing that genuinely hurts is aggressive lossy compression. Psychoacoustic codecs throw away what a human ear won't notice, and a model isn't a human ear. Below roughly 64 kbps mono, fricatives start smearing — the difference between "fifteen" and "fifty" lives in exactly the high-frequency detail a low bitrate discards. Above 128 kbps, in practice, you're fine.
The five formats, ranked for transcription
WAV — the reference
Uncompressed PCM, up to 192 kHz and 32-bit. Nothing has been thrown away, so nothing can be missing. The cost is size: about 10 MB per minute at CD quality. Use it when you own the microphone.
FLAC — the sensible default at volume
Bit-for-bit identical to WAV when decoded, at roughly half the size. If you're running an archive or a nightly batch job over thousands of hours, FLAC is the format that makes the storage bill survivable without touching accuracy.
AAC — the best lossy option
More efficient than MP3 at the same bitrate, which means cleaner speech at a given file size. It's the audio codec inside nearly every MP4, every M4A, and most streaming pipelines.
MP3 — universally supported, technically dated
At 128 kbps and above, MP3 transcribes well. Below that, it degrades faster than AAC. Its real advantage is that everything on earth can play it.
M4A — a container, not a codec
M4A is AAC audio in an MP4 container. Voice Memos produces it, most Android recorders produce something similar. There's no reason to convert it before uploading.
Can APIs transcribe MP4 files?
Yes. Speech-to-text APIs, including AssemblyAI's, accept MP4 files directly — you do not need to extract the audio track first. The API demuxes the file, transcribes the audio stream, and ignores the video entirely. The same applies to MOV, MKV, AVI, WMV, and WebM.
Two practical notes. First, the audio inside an MP4 is almost always AAC, so an MP4 transcribes about as well as the M4A you'd have pulled out of it. Second, you're uploading the video bytes too, which can mean a 2 GB file for 20 minutes of 4K footage. If you're transcribing video at scale and bandwidth is the bottleneck, extracting the audio track with ffmpeg before upload will cut transfer time by an order of magnitude. It won't change the transcript.
How big can an audio file be?
It depends on which endpoint you're calling, and this is the constraint that catches people out mid-build.
The standard async API is built for long files — full podcast episodes, day-long depositions, hours of call recordings — and you submit a job, then poll or receive a webhook when it's done. Check the API documentation for the current size and duration ceiling before you design around it.
The Sync API, which went GA on July 14, 2026, is the opposite trade. One request in, transcript out, no submit-and-poll loop. Median latency is around 134ms for short clips, and it's priced at $0.45/hr. The catch is a hard cap of 40MB or 2 minutes, whichever comes first.
That 2-minute limit is a real design constraint, not a footnote. Voice notes, command utterances, dictated fields, and short user-generated clips fit comfortably. A lecture or an interview does not. There's also a /warm endpoint that pre-warms the connection so DNS, TCP, and TLS setup happen before the user starts talking rather than inside your latency budget.
Format matters more here than anywhere else, incidentally. A 40MB cap is roughly 20 minutes of 16 kHz mono WAV but many hours of AAC — so at the Sync API's 2-minute duration limit, the file size ceiling never binds unless you're sending uncompressed multichannel.
Streaming: PCM or AAC?
16-bit PCM has always been the default for real-time transcription over a WebSocket, and it's still the safe choice. It's trivially cheap to produce, adds no encode latency, and every audio stack on every platform emits it.
But PCM is enormous on the wire. 16 kHz 16-bit mono is 32 KB every second, per stream, forever. On a mobile client over cellular, or a server fanning out thousands of concurrent sessions, that adds up fast.
Streaming now accepts AAC in ADTS framing — set encoding=aac on the connection and send AAC frames instead of raw PCM. Network I/O drops to roughly a sixth of PCM. For a mobile app, that's the difference between a stream that holds up on a weak connection and one that doesn't. For a fleet of concurrent sessions, it's a straight bandwidth cost reduction.
The models on the other end of that socket are Universal-3.5 Pro Realtime at $0.45/hr, which handles 18 languages with mid-sentence code-switching and is the speech foundation under our Voice Agent API, and Universal-Streaming English at $0.15/hr when you need the lowest possible latency and only ever speak English. Full breakdown on the pricing page.
Does converting formats improve accuracy?
No, and this is the single most common mistake in audio preprocessing.
Converting an MP3 to WAV does not restore what the MP3 encoder discarded. The information is gone. You now have a file several times larger containing exactly the same degraded audio, plus whatever artifacts the second encode introduced. Transcode only when you need a different container, never as a quality step.
Noise reduction deserves the same skepticism. Aggressive denoising distorts the speech signal alongside the noise, and modern acoustic models are trained on messy real-world audio — they've heard air conditioning before. Heavy-handed cleanup often makes transcripts worse.
What does help: normalizing volume when levels are wildly inconsistent across a batch, and trimming long stretches of silence so you're not paying for dead air. Both are safe because neither touches the spectral content of the speech itself.
Choosing a format for your use case
You control the recording and accuracy is the priority. Record 16 kHz mono WAV, 16-bit. Send it to Universal-3.5 Pro at $0.21/hr, which averages 4.35% normalized word error rate across our evaluation datasets — see the full benchmark results for the per-dataset breakdown.
You're building a web or mobile app. Take whatever the device gives you. M4A from iOS, AAC or MP3 from a browser's MediaRecorder. Don't add a conversion step to a user-facing upload flow to chase an accuracy difference you won't be able to measure.
You're processing video. Send the MP4. Media platforms do this at enormous scale — Veed, the browser-based video editor, put it this way:
"Assembly allowed our team to focus on what they are best at: Building a collaborative, browser-based video editor and distributing that product at speed and at velocity to our user base." — Sabba Keynejad and Tim Mamedov
Kapwing runs a similar workflow on user-uploaded media in every format the open web produces. You can see more of how teams build on the API across formats and media types.
You're archiving at volume. FLAC. Lossless, roughly half of WAV, and you'll never have to re-record anything because a codec decision aged badly.
The format is rarely the problem
Here's the thing worth taking away. In nearly every case where someone brings us a disappointing transcript and asks whether they should switch formats, the format isn't the culprit. It's a microphone across the room, a speaker on a bad phone line, four people talking over each other, or a technical vocabulary the model has never encountered.
Those are all solvable — with better capture, with multichannel recording, with the right speech-to-text setup for the audio you actually have. But none of them get solved by re-encoding a file. Pick a sane format, spend the effort on the microphone, and move on.
Frequently asked questions
What file formats do transcription APIs support (MP3, WAV, etc.)?
Most modern transcription APIs accept every common audio and video container: WAV, FLAC, MP3, AAC, M4A, OGG, OPUS, WMA, plus MP4, MOV, MKV, AVI, and WebM on the video side. AssemblyAI accepts all of these directly with no pre-conversion. If a format is genuinely unsupported, the API returns an error rather than a bad transcript, so you'll know immediately.
Can APIs transcribe MP4 files?
Yes — you can send an MP4 straight to a transcription API and it will extract and transcribe the audio track for you. There's no need to demux with ffmpeg first. The only reason to extract audio yourself is to reduce upload size, since you'd otherwise be transferring the video data for nothing.
What is the maximum audio file size supported by a transcription API?
It depends on the endpoint, not the format. AssemblyAI's Sync API caps requests at 40MB or 2 minutes of audio, whichever comes first, because it's built for immediate single-request responses. The standard async API handles far longer files — full-length recordings measured in hours — so check the API reference for the current ceiling before designing around it.
How to send multi-channel (stereo) audio to a transcription API?
Enable multichannel on the request and the API transcribes each channel separately, returning results labelled by channel. This is the cleanest possible speaker separation when your recording setup already isolates participants — a conference bridge or a call center recorder with one track per party. If everyone shares one channel, use speaker diarization instead.
What is the most reliable speech-to-text API for podcast transcription?
For podcasts, look for three things: strong accuracy on conversational multi-speaker audio, reliable speaker diarization, and pricing that survives a back catalogue. Universal-3.5 Pro handles all three, jointly producing the transcript and the speaker changes in a single pass so short interjections and crosstalk survive. Feed it the highest-quality master you have — if you still have the pre-publish WAV or FLAC, use that rather than the released MP3.
Can transcription services process streaming audio?
Yes. Streaming transcription runs over a WebSocket and returns partial results as the person is still speaking, typically within a few hundred milliseconds. AssemblyAI's streaming endpoint accepts 16-bit PCM or AAC in ADTS framing, with AAC cutting network traffic to roughly a sixth of PCM. Streaming is billed on how long the session stays open rather than how much audio you send.
Lorem ipsum dolor sit amet, consectetur adipiscing elit, sed do eiusmod tempor incididunt ut labore et dolore magna aliqua. Ut enim ad minim veniam, quis nostrud exercitation ullamco laboris nisi ut aliquip ex ea commodo consequat. Duis aute irure dolor in reprehenderit in voluptate velit esse cillum dolore eu fugiat nulla pariatur.